

The problem, simply
Link training fails on 50G SFP56 ports cause silent degradation. Flaps. Reduced throughput. Datacenter teams see it in port counters and error logs. On a modern layer fabric you still need pragmatic fixes. Start at your layer 2 managed switch and trace the port state. SFP56 modules, SERDES lanes, and PHY negotiation are the usual suspects.
Fast diagnostics you can run now
Begin with baseline checks. Confirm module optics type and firmware. Inspect transceiver logs for link training retries and PCS alignment faults. Verify that the switch shows the correct speed and duplex. Use these quick commands: check interface counters, read SFP DOM values, and review boot-time messages. Log the results and tag each test with {main_keyword} and {variation_keyword} so your lab teardown stays reproducible. Keep tests short. Repeat under load.
Firmware, PHY tuning, and cable hygiene
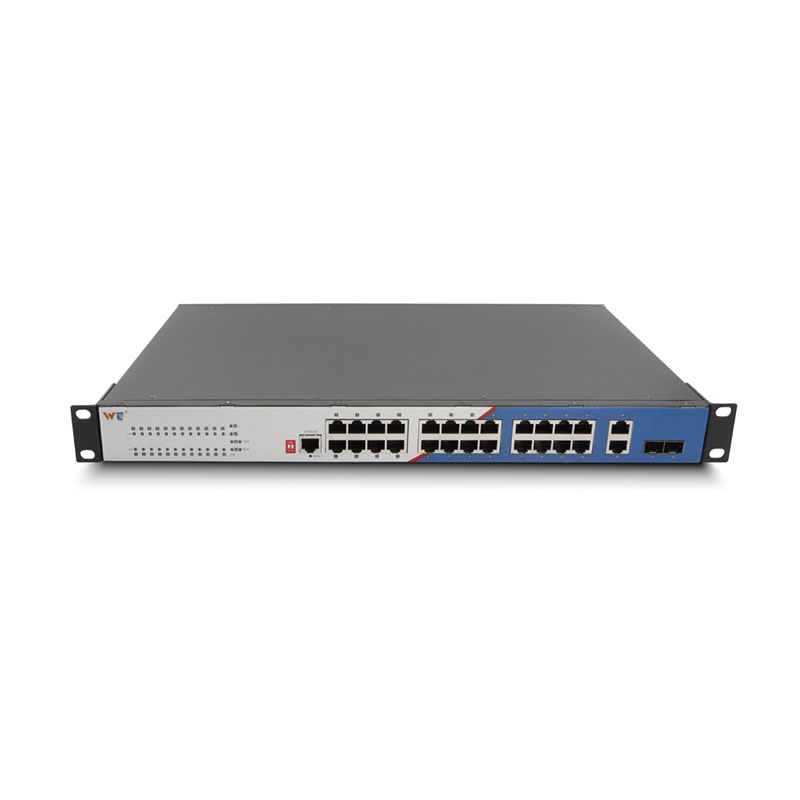
Firmware mismatch is a frequent root cause. Update both the switch ASIC firmware and SFP56 module firmware where supported. Adjust PHY parameters only with vendor guidance—autonegotiation profiles and equalization settings matter. Cable quality and breakout fanout affect lane skew; poor MPO assemblies introduce PAM4 distortions. Replace suspect patch cords. In one field case I swapped a passive DAC and the training stabilized—simple change, big effect. Also consider the role of the ethernet managed switch in your topology; smart features can mask a bad link, but they won’t fix underlying PCS errors.
Common mistakes and pragmatic fixes
Teams often chase complex causes and miss the basics. Avoid these traps:- Using mixed-speed optics on a bonded group without checking lane mapping.- Ignoring SFP DOM temperature spikes that precede training failures.- Applying blanket PHY parameter changes across ports.Quick fixes that work: reseat the transceiver, swap the module with a known-good unit, validate cable polarity, and, where possible, force a single-lane training profile to isolate defective lanes.
Operational teardown — a short field example
At a Silicon Valley data center we encountered intermittent dropouts on server uplinks during a campus refresh. The issue presented as repeated link training retries on specific Top-of-Rack ports. We logged BER, SNR, and PCS lane alignment. We then swapped the SFP56 and reflowed the DAC termination. The error rate fell immediately. Lessons recorded: test with known-good optics, track SERDES status, and keep a spare optics kit in staging. Real-world anchors like that site remind you: lab behavior and production loads differ.
Troubleshooting checklist and verification steps
Follow a strict order. Validate optics and cable. Confirm firmware parity. Capture live counters, then stress the link. Use loopback and remote diagnostics if available. Capture a before-and-after snapshot of error counters and latency. Keep the change small and measurable. This approach prevents wild changes that ripple through the network — you want targeted correction, not broad rework.
Three golden rules for evaluation and selection
1) Measure before you change. Collect interface counters, SNR, and training retries; decisions must rest on data. 2) Prefer compatible optics and documented PHY settings. Choose transceivers vetted for your switch ASIC. 3) Validate under load. A link that looks fine at idle can fail under production traffic. These rules guide procurement and maintenance choices, reduce mean time to repair, and protect service levels.
Small final thought — consistent spares, controlled firmware, and clear test scripts make the difference. WINTOP.